

Introduction
Issues with AI-generated code
In early 2026, I performed interviews with 26 builders working for
a company that was closely invested in growing with AI coding
brokers. Certainly one of my questions was “do you belief our exams?” In spite of everything, the
builders had been from Thoughtworks, and Thoughtworks prides itself on the
high quality and thoroughness of our testing. Sadly, the builders
invariably answered “Effectively… I don’t belief our exams that a lot! As a result of
even when I assessment the exams when they’re initially generated, as new
options get added, the AI refactors each present code and present
exams, so I’m now not assured that the exams are nonetheless making certain the
proper behaviour”.
This received me pondering. As we be taught to get extra work carried out from coding
brokers, it’s changing into pure that AI writes most, if not all of the exams.
The follow of builders writing automated exams was a significant
breakthrough in software program engineering within the late twentieth century. Probably the most
sensible means to do that is to put in writing the exams earlier than the code
(test-first) and to put in writing and make go one take a look at at a time (test-driven
improvement). This follow allowed groups growing enterprise software program
to ship practically bug-free code, at a fraction of the price of formal
specs and proofs.
In 2026, loads of code is written by AI coding brokers, and people
brokers will generate exams even with out asking, so one may hope that
we will obtain the identical stage of correctness that human coders loved
with TDD. Sadly, it’s a typical expertise that this isn’t the
case. The truth is, there have been quite a lot of stories revealed in early
2026 displaying that the standard of code being deployed by organizations is
getting worse.
I don’t know for sure what the causes are of this extensively reported lower in exterior high quality,
however I feel it’s believable that one of many causes could also be a decline in high quality of the automated
useful exams.
Issues with AI-generated exams
After we give excessive autonomy to AI to generate code, we have to belief
the AI to put in writing good exams, as the choice of writing all of the exams
by hand is now not life like. Let’s get again to the issue reported
by the builders who stopped trusting the exams when the AI
refactored them. Why does the AI refactor the exams? Almost definitely, it
must refactor them as a result of the signature of a perform adjustments as
the code evolves, and that is anticipated to occur in the midst of
improvement, so the AI is just not “flawed” when it does this. However studying
AI-generated take a look at code is much more boring than studying AI-generated
manufacturing code, so it’s not life like to anticipate builders to
rigorously re-read all modified take a look at code at each step.
One other downside with AI-generated exams is that they is likely to be
tightly coupled to the implementation. If we ask a coding agent to
“cowl module X with unit exams”, it is going to fortunately generate loads of
exams, and sometimes these exams will use a lot of mocks and stubs.
The aim of exams is to interrupt when the code returns the flawed
end result, or produces the flawed negative effects. Sadly, exams that
use mocks and stubs closely have a tendency to interrupt each time the implementation
of the stubbed and mocked code adjustments, even when the change is a
innocent refactoring that preserves correctness. So these exams
produce loads of false positives. What’s worse is that these exams
may not give us confidence that they’ll shield us when the code
does the flawed factor. As an alternative of proving that “when enter is X, output
should be Y”, these exams may simply show that “after we invoke perform
A, it is going to invoke perform B”, which isn’t helpful, as a result of it’s not
proving that the code will produce the proper outcomes. The truth is, when
we ask AI to cowl one thing with exams, we’d just like the exams to
specify the proper behaviour, however most frequently, the AI will write exams
that verify the present implementation, together with any bugs it could
comprise.
So in abstract, AI-generated exams are sometimes problematic
as a result of:
- The amount of take a look at code is giant
- Check code is difficult to learn
- The exams are coupled to the implementation, and
- They may not even show that the code is right
We may mandate that human builders write all of the exams, and
write good exams, however this can negate many of the anticipated financial
good thing about coding brokers, and isn’t life like given the place software program
engineering appears to be heading. However what if there was a option to write
exams that’s a lot simpler for people to each learn and write? That is
what we’ll cowl in what follows.
Issues with AI-generated specs
A variety of AI-assisted improvement is finished utilizing some type of spec-driven improvement:
distributors advocate it and
some SDD frameworks are highly regarded. Whereas it appears clear that aligning with AI earlier than improvement is
very helpful, e.g., by getting the AI to ask clarifying questions, there are issues with the era
of “specs” written as prose in Markdown paperwork.
One downside is that, once more, the amount of generated prose makes it arduous for builders to learn all of it.
After a degree, fatigue kicks in and we danger accepting the AI-generated plans after little greater than a
cursory look, in what somebody referred to as cognitive give up. One other downside is
upkeep: as soon as a function is full, what can we do with all of the specs? Some frameworks help
sustaining a set of sturdy specs, however the danger, once more, is that over time the amount of those specs develop
too giant for upkeep. A 3rd downside is that large-language fashions don’t adjust to the entire
detailed specs; it may well occur that the AI provides up on some components of the spec with the intention to declare
“carried out” sooner.
Lastly, and most essentially, English is ambiguous: whereas we will attempt to specify what we would like as
exactly as we will, pure language doesn’t afford the extent of precision that we
get with programming languages. In brief, prose specs cannot be executed; exams can.
What I’m proposing
Our objective is to have exams that exhibit these properties:
- They predict success
in manufacturing: when all of the exams go, it provides us confidence that the performance is
applied appropriately and it’ll behave as anticipated in manufacturing - They’re proof against refactoring
- They’re as straightforward to learn as attainable
To realize this, we suggest these methods:
- Buyer exams: write within the language of the client.
- Black field: take a look at the system, or parts of the system from the surface, with out
mentioning implementation particulars of the manufacturing code. - Checks-as-data: concentrate on the vital particulars: the enter, the anticipated output or aspect
results, and the take a look at setup. In different phrases, the take a look at ought to seize simply the details, with out
mentioning implementation particulars within the take a look at code. - Check DSL: discover essentially the most simple methods to signify the enter, the output and the
system state in textual content that may be understood by a site knowledgeable, and produces a clear diff
when the take a look at fails.
When AI writes the code, the builders turn out to be in a means prospects. The exams are a contract that
establishes what the code ought to do for us, and shifting exams to information recordsdata, interpreted by a comparatively smaller take a look at runner,
makes them simpler to guard from sudden manipulation by AI.
The identical AI makes it straightforward to put in writing take a look at runners that run our take a look at DSLs.
The place does this go away TDD? Given how a lot people profit from TDD when coding, can we anticipate AI to
do a greater job after we ask it, or pressure it, to make use of TDD in its inside coding loop? Getting AI to observe
canon TDD is just not straightforward, as a result of AI often
generates a lot of code earlier than writing exams. However, evidently coding brokers carry out
higher after we simply inform them what we would like and the way to validate the end result: including
directions on the way to obtain the end result appears to make
them carry out worse.
The methods mentioned right here present the “the way to validate the end result” that coding brokers want. In a
means, we may see this as a option to do test-first, with bigger steps. Typically talking, taking smaller
steps makes improvement safer; nonetheless, the objective of this text is to debate methods to allow taking
bigger steps safely.
Core methods
Buyer exams
Builders writing exams was one of many unique practices of
Excessive Programming. The ensuing exams are typically referred to as
“developer exams” as a result of they help builders in making certain that
their code does what they assume it ought to. (Most builders name them
unit exams.) One other one of many unique XP practices was Buyer
exams, also called Acceptance exams.
A buyer take a look at is a take a look at written within the language of the client;
it describes what the software program ought to do, from the standpoint of the
customers.
The thought is {that a} buyer can perceive what a buyer take a look at is making an attempt to
show, in order that these exams assist convey alignment between buyer and builders.
The attention-grabbing half is that when a machine is writing many of the code, the
human builders begin enjoying increasingly more the a part of the “prospects” of the
code. We’re eager about specifying what the software program ought to do, in phrases that
are as freed from implementation particulars as we will, as a result of we’re delegating these
implementation particulars to the AI.
The circles of Excessive
Programming practices. Picture by Ron Jeffries, used with permission.
That is why I feel that buyer exams are the
main sort of exams that we must always depend on; particularly when
manufacturing code is AI-generated. Unit exams (developer exams) can
nonetheless be helpful, however we don’t deal with them as the first supply of
reality the place specifying behaviour is anxious.
Buyer exams:
- Outline the useful content material of a person story, in order that once they go, we
know that the story is functionally full - Shield us in opposition to regressions: as soon as a buyer take a look at passes, it should at all times
go, till the enterprise rule that it’s testing adjustments - Help refactoring, as a result of they take a look at behaviour, not implementation
- Final however in all probability most vital: they’re a device for making certain alignment
between builders and prospects. The purchasers can learn and perceive the
take a look at, and might present suggestions to make sure that we’re testing the appropriate
factor.
However, buyer exams may show troublesome to work
with. Particularly when they’re applied as end-to-end exams, they
may be sluggish and flaky. There are methods to beat these issues,
and we are going to talk about them within the coming sections.
Give attention to what issues
Let’s examine how we will repair the issue of hard-to-read exams.
Think about the next easy instance:
@Check
void defaultGreeting() throws IOException, InterruptedException {
    HttpRequest request = HttpRequest.newBuilder()
            .uri(URI.create(baseUrl + "/hi there"))
            .GET()
            .construct();

    HttpResponse response =
            consumer.ship(request, HttpResponse.BodyHandlers.ofString());

    assertEquals(200, response.statusCode());
    assertEquals("Good day, world!", response.physique());
}

@Check
void personalisedGreeting() throws IOException, InterruptedException {
    HttpRequest request = HttpRequest.newBuilder()
            .uri(URI.create(baseUrl + "/hi there?title=Joe"))
            .GET()
            .construct();

    HttpResponse response =
            consumer.ship(request, HttpResponse.BodyHandlers.ofString());

    assertEquals(200, response.statusCode());
    assertEquals("Good day, Joe!", response.physique());
}
Are you able to instantly spot what the exams are attempting to show? A
educated eye will concentrate on the vital bits, which are highlighted
beneath:
@Check void defaultGreeting() throws IOException, InterruptedException { HttpRequest request = HttpRequest.newBuilder() .uri(URI.create(baseUrl + "/hi there")) .GET() .construct(); HttpResponseresponse = consumer.ship(request, HttpResponse.BodyHandlers.ofString()); assertEquals(200, response.statusCode()); assertEquals("Good day, world!", response.physique()); } @Check void personalisedGreeting() throws IOException, InterruptedException { HttpRequest request = HttpRequest.newBuilder() .uri(URI.create(baseUrl + "/hi there?title=Joe")) .GET() .construct(); HttpResponse response = consumer.ship(request, HttpResponse.BodyHandlers.ofString()); assertEquals(200, response.statusCode()); assertEquals("Good day, Joe!", response.physique()); }
By specializing in the take a look at title, the enter and the anticipated
output, it turns into clear that the exams are attempting to show: the
normal greeting is “Good day, world!”, and the greeting when a
title is supplied is “Good day,
is boilerplate that makes seeing the take a look at intent more durable.
So
why do not we concentrate on simply these three issues? What if we simply
wrote one thing like
suite: greetings
exams:
  - title: "default greeting"
    request:
      useful resource: "/hi there"
      title: null
    greeting: "Good day, world!"
  - title: "personalised greeting"
    request:
      useful resource: "/hi there"
      title: "Joe"
    greeting: "Good day, Joe!"
This yaml file can be utilized as a supply of take a look at instances by a
parameterized take a look at that could be very straightforward for the AI to put in writing. A
regular course of can be:
- Draft a pattern of the take a look at domain-specific language (DSL)
that you just’d wish to have - Get the AI to put in writing a take a look at runner for it
- Each human and AI combine another helpful take a look at instances; for
occasion
- title: "title should not be completely whitespace"
  request:
    useful resource: "/hi there"
    title: " "
  error: "Title should not be completely whitespace"
We will make this much more concise by extracting a desk that
may be saved in a CSV file
test_name,             useful resource, title, greeting,         error
default greeting,      /hi there,   null, "Good day, world!",
personalised greeting, /hi there,   Joe,  "Good day, Joe!",
not whitespace,        /hi there,   " ",  null,             Title should not be completely whitespace
Why tables? As a result of a desk makes it straightforward to see at a look what
instances are lined, and what instances could also be lacking. As well as, a
desk makes it simpler so as to add new take a look at instances.
This, in essence, is tests-as-data. How does this assist with the issue of
builders not trusting exams? It helps as a result of the exams are (1) targeted on the
half that’s of most curiosity to us as developer-customers, (2) extra proof against
refactoring, and (3) when the exams are written in textual content recordsdata, it is simpler to
spot when AI is altering them.
Tables work effectively when the enter to the appliance, the setup state and the anticipated
output are single, scalar values. When they’re structured information, we have to use
structured eventualities, lined beneath.
Not all exams can slot in tables
When the inputs of the take a look at aren’t a easy worth, the tabular format doesn’t suffice. We will then flip to extra structured eventualities. My first publicity to the thought of buyer exams got here from Ron Jeffries’ guide Excessive Programming Adventures in C#, revealed in 2004. He describes the event of an editor for articles with XML markup, and begins with this buyer take a look at (rewritten for readability):
---- earlier than ----Fo|o
Bar
---------------- * press enter ---- after ----Foo
|
Bar
----------------
The intent of the take a look at is to indicate what ought to occur when the person presses the enter key when the cursor, represented by the “|” character, is in the midst of a paragraph. Jeffries continues displaying how you would write a easy runner for this take a look at. From the start, this buyer take a look at lives in a textual content file.
One other instance: when growing programming language interpreters or compilers, I at all times thought that
the waterfall method of designing the grammar first after which every processing stage is much less efficient
than beginning with the best significant program you may outline, which for many languages is a “Good day,
world!”, after which constructing language options one take a look at at a time. Working this fashion with coding brokers makes
it attainable to put in writing very sophisticated interpreters and compilers safely. Right here’s an instance from a BASIC
interpreter experiment, and this method scales to rather more sophisticated languages.
exams:
  - title: "LEN perform fundamental exams"
    program: |
      10 PRINT LEN("HELLO WORLD")
      20 PRINT LEN("")
      30 PRINT LEN("A")
      40 END
    anticipated:
      - "11n"
      - "0n"
      - "1n"
  - title: "LEFT$ perform fundamental exams"
    program: |
      10 PRINT LEFT$("HELLO WORLD", 5)
      20 PRINT LEFT$("HI", 10)
      30 PRINT LEFT$("TEST", 0)
      40 PRINT LEFT$("HELLO", 3)
      50 END
    anticipated:
      - "HELLOn"
      - "HIn"
      - "n"
      - "HELn"
How would we take a look at an online software? Right here’s an concept for testing a easy todo-list app:
## Unchecking a accomplished todo reactivates it
GIVEN mannequin:
    [x] purchase milk
    [ ] stroll the canine
WHEN person:
    click on toggle of "purchase milk"
THEN web page:
    > ""
    [ ] purchase milk
    [ ] stroll the canine
    -- **2** objects left
THEN mannequin:
    [ ] purchase milk
    [ ] stroll the canine
The show of the appliance, that renders like this:
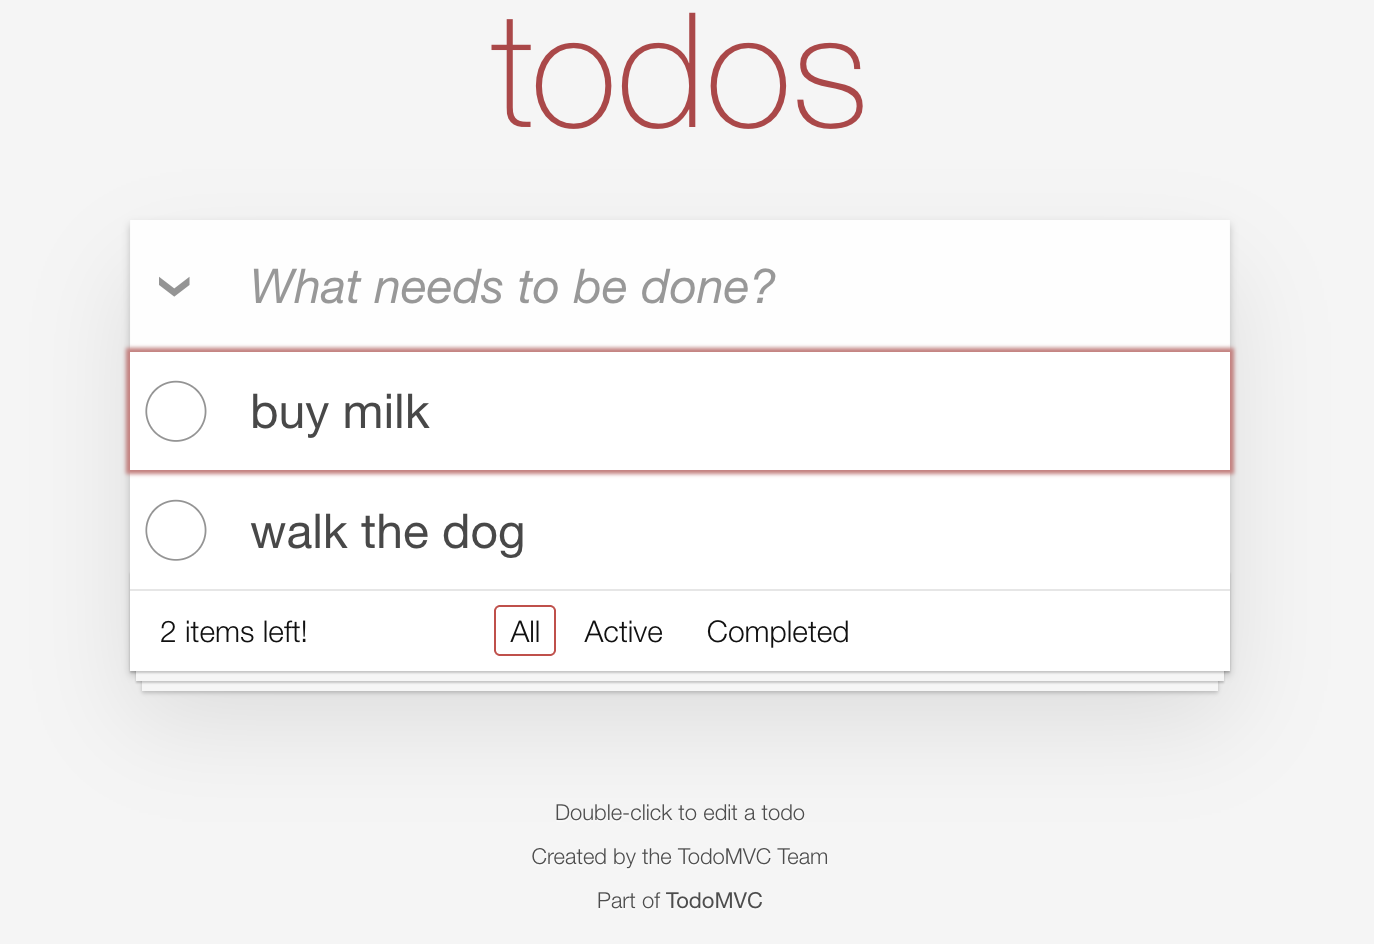
is simplified from the unique HTML to this:
> ""
[ ] purchase milk
[ ] stroll the canine
-- **2** objects left
This textual illustration is straightforward to insert in exams, it produces a transparent “diff” when a take a look at fails,
and is powerful in opposition to adjustments within the visible look of the UI. The perform that transforms the HTML,
or the DOM, to this textual illustration is named a “projection”, or extra merely, a printer.
On this instance we use one other printer, that exhibits the contents of the inner state of the
software. It is within the THEN mannequin part and it makes use of a syntax much like the one
produced by the UI printer. It was added as a result of when testing an operation that’s supposed to alter the
state, like on this case unchecking a todo merchandise, we shouldn’t be glad with simply seeing the
change within the UI: we might like to make sure that the persistent state of the appliance was modified as
effectively.
Alongside the 2 printers, on this instance we additionally make use of two parsers: the primary one is used
within the GIVEN mannequin part, the place the beginning state for the take a look at is represented, and is used
to arrange the appliance state the way in which the take a look at wants it to be. The second parser is used within the
WHEN person part, to parse the command that we ship to the appliance. Its job is to
acknowledge a vocabulary of operations that may be utilized.
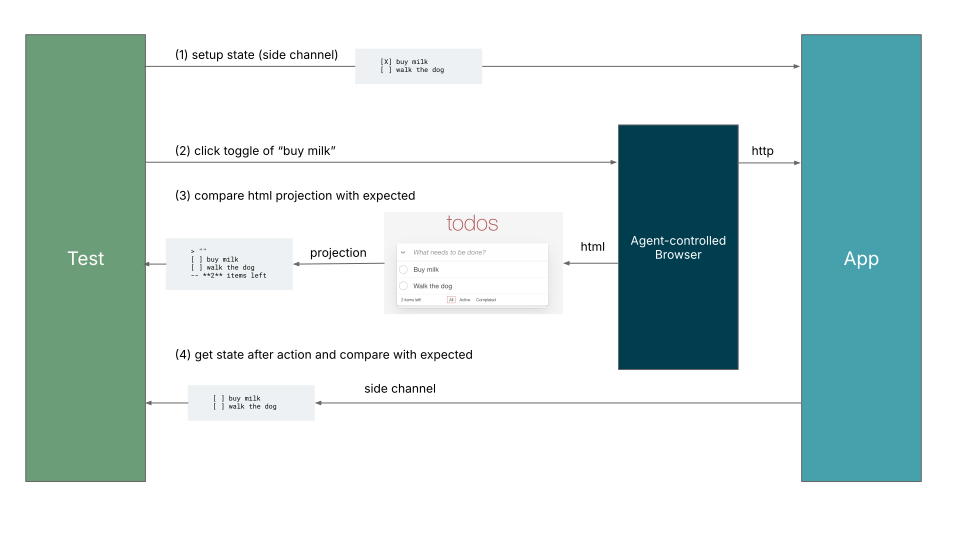
Sequence diagram displaying how the todo-list take a look at works.
The printer and parser for the appliance state will need to have some option to entry and manipulate the appliance state itself; this may be achieved via a aspect channel.
The entire above mechanisms are used collectively in a take a look at runner {that a} coding agent can simply generate.
Constructing on present traditions
Match and specification by instance
Ward Cunningham is credited as originator of lots of the concepts
that later had been popularized in Excessive Programming. Cunningham tells
about how across the 12 months 2002, his prospects tended to offer
their very own specs in Excel paperwork. Drained
of copying the take a look at information from Excel to check code, he wrote a
program that learn the take a look at information from Excel and
executed the exams robotically. This made it very straightforward for his
prospects to increase and refine the specification, and for him to
confirm that his applications matched the specification itself. He
referred to as this device Match and it has implementations
for varied programming languages.
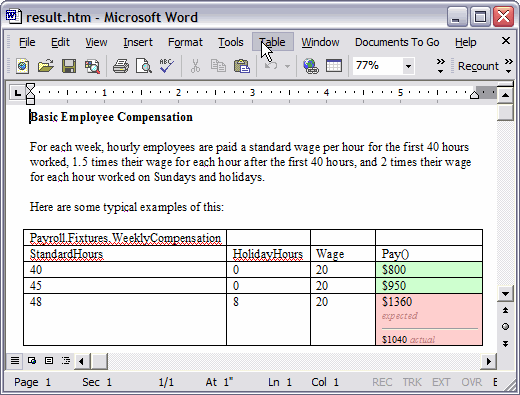
A screenshot of Match displaying the outcomes of a take a look at. Picture by James Shore, used with permission.
In 2004, Martin Fowler revealed his article on Specification
by
Instance,
that just about sums up the thought: sophisticated necessities may be
clarified by getting builders and enterprise folks to agree on
examples of what ought to occur. Later, in 2011, Gojko Adzic
revealed a guide with the identical
title, and by
then quite a lot of related approaches had been rising, the preferred
being Cucumber and its language
Gherkin.
The Specification by Instance custom popularized buyer
exams; however the method was not with out prices. Automating the
extraction of tables from doc may be sluggish and fragile, and
Cucumber requires a layer of interpretation code that typically can
be a supply of bugs and misunderstandings.
James Shore was an early adopter of Match, and maintained lots of its implementations. He later grew to become disillusioned with the method, lamenting that, whereas the first goal of the device is to enhance communication with prospects, most prospects didn’t need to write the take a look at tables, which led him to have the conversations with the purchasers after which write the Match exams himself. Later, utilization of Match (and Gherkin) was generally delegated to QA groups to check software program after-the-fact, which defeats the unique goal of facilitating a dialog with the purchasers. For these causes, he reckoned that if the purchasers will not write the exams, then the upkeep overhead of the Match or Gherkin runners is just not well worth the worth, and writing exams in code makes extra sense.
The truth that prospects do not need to write buyer exams is usually quoted in opposition to the follow of buyer exams. I feel that the state of affairs we’re in in the present day adjustments this reality, as a result of:
- When the AI writes most manufacturing code, then human builders are within the place of shoppers: we
describe what we would like, and supply suggestions on what we get, similar to prospects have at all times carried out. - Writing and sustaining the equipment that runs the client exams is one thing that coding brokers can do rapidly and cheaply.
Specification by instance may also help with the issues with spec-driven improvement described within the introduction, by clarifying the acceptance standards with examples, in order that their description may be a lot shorter. By making these exams an integral a part of the specification, we make the specification executable and unattainable to bypass by the coding brokers. And these specs can’t go stale, as a result of they run in CI.
Testing practices in Go
A associated method comes from the custom of the Go programming
language, the place most exams are tabular. For instance, right here is how the
“fmt” bundle is examined:
var fmtTests = []struct {
    fmt string
    val any
    out string
}{
    {"%d", 12345, "12345"},
    {"%v", 12345, "12345"},
    {"%t", true,  "true"},

    // fundamental string
    {"%s",    "abc",              "abc"},
    {"%q",    "abc",              `"abc"`},
    {"%x",    "abc",              "616263"},
    {"%x",    "xffxf0x0fxff", "fff00fff"},
    {"%X",    "xffxf0x0fxff", "FFF00FFF"},
    {"%x",    "",                 ""},
    {"% x",   "",                 ""},
    {"%#x",   "",                 ""},
    {"%# x",  "",                 ""},
    {"%x",    "xyz",              "78797a"},
    {"%X",    "xyz",              "78797A"},
    {"% x",   "xyz",              "78 79 7a"},
    {"% X",   "xyz",              "78 79 7A"},
    {"%#x",   "xyz",              "0x78797a"},
    {"%#X",   "xyz",              "0X78797A"},
    {"%# x",  "xyz",              "0x78 0x79 0x7a"},
    {"%# X",  "xyz",              "0X78 0X79 0X7A"},
    //[...]
The above creates an array of structs composed of: the format
being examined, eg “%x”, the enter string, eg “abc”, and the ensuing
formatted textual content, on this case “616263”. A brief take a look at runner executes
all of the rows on this desk in opposition to the fmt perform. Many features
within the Go normal library are examined in the same means.
Once more in Go, there may be a longtime follow of writing eventualities in textual content recordsdata, significantly when
the take a look at is dependent upon the existence of recordsdata, or checks that recordsdata are created. Right here is an instance of how the go command line device is examined:
env GO111MODULE=off

# hi there world
go run hi there.go
stderr 'hi there world'

-- hi there.go --
bundle fundamental
func fundamental() { println("hi there world") }
We see that a customized DSL was developed for the aim of testing the central Go utility program. The take a look at workouts the go run subcommand. The DSL permits the take a look at author to outline an setting variable, setup a file, execute a command and examine the ensuing output on the usual error channel.
Approval testing
A 3rd related custom is that of Approval
Checks, popularized by Llewellyn Falco, the place it’s common
to get a system to generate a file that
might signify a sequence of computations, or what the UI appears to be like
like at a selected second, or a readable illustration of the
inside state of the system; the primary level is that the
illustration we get is comprehensible by people, who can then
approve it. As soon as a file is accepted, it may be
regenerated in future runs and each time the newly generated file
differs from the accepted one, it alerts that the behaviour of
the system has modified. The mechanism for working these exams
includes a take a look at runner, that may come from an approval testing
library, or may be generated advert hoc by a coding agent. This
method is related for our pursuits right here, as a result of it stresses
that what people take a look at is just not take a look at code, however take a look at information.
One key concept to take from approval testing is to seek out methods to
make software state and output readable and “diffable”, which means
that when a take a look at fails, we will see a clear textual diff between
what was anticipated and what we received.
Llewellyn Falco and Lada Kesseler give an excellent rationalization of Approval Testing in
follow (video)
Accredited Eventualities and Accredited Logs
Ivett Ördög has been selling the methods I am describing on this article for a while. She revealed the Accredited Eventualities and Accredited Logs patterns, the place she advocates utilizing a domain-specific language to precise buyer exams. The primary sample is for after we specify behaviour upfront; the second depends on the working system to generate a textual illustration of its state, that may be tweaked and used to generate new exams, particularly when testing present methods, or writing a failing take a look at as step one in direction of bug fixing. Her video explains the methods in additional element.
A typical Accredited Situation or Accredited Log DSL consists of three components: the setup of the state of the system, the motion or actions to be executed, and a illustration of the state of the system after the actions. The method by which one would get began is to:
- Determine on a DSL format, seemingly in collaboration with the AI, and write a primary take a look at
- Have a coding agent generate the DSL parser and take a look at runner
- The developer checks that the runner works appropriately, by checking it in opposition to manufacturing code
- The coding agent provides eventualities, utilizing the primary take a look at as a template
My interpretation is that the Accredited Eventualities sample is utilized to a system that has already
sufficient construction to make a significant first take a look at attainable, in a means much like the Spike and Stabilize sample described by
Dan Terhorst-North. Another means, when ranging from scratch, might be that the primary take a look at is
used to generate a
Strolling Skeleton.
The 2 patterns are situations of what Ördög calls the Constrained Checks sample, the place a coding agent can’t simply “cheat” by writing exams which are weaker than anticipated. Accredited Eventualities and Logs make dishonest much less seemingly, by making the assertion a part of the take a look at necessary within the DSL syntax, and this requires that the DSL is applied with a parser, i.e. an exterior DSL.
Ördög argues that if we implement an inside testing DSL, which is just a
assortment of features outlined within the programming language we’re utilizing, then an agent may write exams
with no assertions, or weak assertions, thus faking a excessive take a look at protection rating whereas the exams aren’t
testing the system as anticipated. An exterior DSL, the place the assertions are an integral and necessary half
of the DSL syntax, makes this downside much less seemingly.
So, one goal of the Constrained Checks sample is to make sure that take a look at protection is a dependable indication of what components of the code are examined, and this makes the overhead and indirection of an exterior DSL worthwhile.
Implementation hints
Not at all times end-to-end
It’s common to implement buyer exams as end-to-end exams
passing via the UI. This may be OK, however it isn’t the one
means. One downside with all buyer exams being end-to-end is
that the exams turn out to be slower, and extra fragile. A great way to
keep away from that is to execute most exams bypassing the UI. Many
enterprise purposes have a service
layer,
that could be a set of lessons, or features, which are invoked by the
UI and by different entry factors within the system, to execute enterprise
operations. The exams can invoke the service layer, bypassing
the UI completely. This is sensible in lots of domains the place logic is
rather more sophisticated and troublesome to get proper than the UI,
for instance within the monetary area. An instance from my
expertise was when, within the insurance coverage area, we got a
sophisticated algorithm for matching a declare with a lawyer.
Writing the client exams helped us make certain we understood
precisely what the client needed to attain, and we applied
it as a service-level take a look at.
One other downside is when the entry level of your take a look at is way,
when it comes to variety of perform calls, from the logic that you just
need to train.
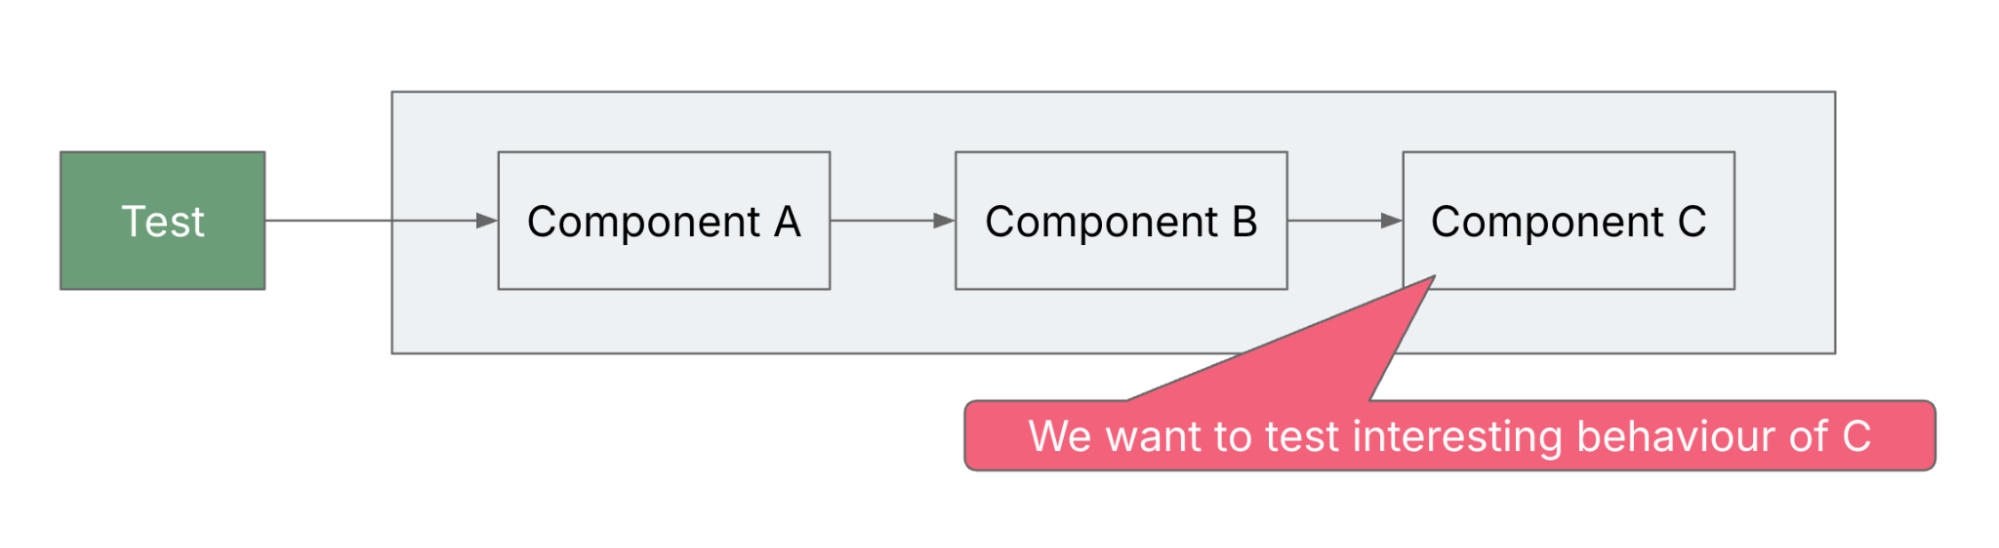
On this instance, we need to take a look at some attention-grabbing logic in a
part “C”, however so as to take action, our take a look at should “persuade” the
intervening part “A” to arrange appropriately part “B” in
a means that it units up appropriately part “C”. This may be
awkward, and should result in a sense of making an attempt to construct a ship in a
bottle, making an attempt to arrange tiny particulars utilizing sticks via the
opening of the bottle.
We don’t have to do that; when we have now an vital part
that we need to specify intimately, we will write buyer exams for
it straight. Do not forget that a very powerful factor a couple of
buyer take a look at is that it helps alignment between prospects and
builders. An instance is that this take a look at for a part that checks if
the person’s IP handle matches an allowlist. The allowlist was
sufficiently sophisticated that we didn’t really feel assured testing it
with end-to-end exams alone, so we wrote a targeted buyer take a look at,
applied as a unit take a look at, full with its personal customized take a look at
DSL.
exams:
  - title: "is_ip_allowed respects enabled flag"
    allowlist:
      - { id: 1, ip_or_cidr: "10.0.0.1/32", is_enabled: true }
      - { id: 2, ip_or_cidr: "10.0.0.2/32", is_enabled: false }
    is_ip_allowed:
      - { ip: "10.0.0.1", anticipated: true }
      - { ip: "10.0.0.2", anticipated: false }

  - title: "is_ip_allowed fails closed on empty allowlist"
    allowlist: []
    is_ip_allowed:
      - { ip: "10.0.0.1", anticipated: false }

  # --- IPv4 MATCHING ---
  - title: "is_ip_allowed matches /32 vary"
    allowlist:
      - { id: 1, ip_or_cidr: "192.168.1.100/32", is_enabled: true }
    is_ip_allowed:
      - { ip: "192.168.1.100", anticipated: true }
      - { ip: "192.168.1.101", anticipated: false }
      - { ip: "192.168.1.99",  anticipated: false }
Utilizing a take a look at DSL for each vital factor that we need to take a look at
is affordable now, as a result of the AI can construct take a look at runners very
cheaply.
Buyer exams for the UI
Testing UIs is notoriously difficult, however on the identical time, UIs typically comprise vital logic that we
need to take a look at. The challenges come from the slowness and flakiness of most exams that use instruments like
Selenium. Instruments like Playwright may also help cut back take a look at flakiness by automating the look forward to parts to be
rendered. Browser-based part testing was just lately promoted to Trial within the Thoughtworks Expertise Radar.
There are additionally approaches that don’t require working exams via a browser; JSDOM can be utilized by take a look at runners
to mount UI parts right into a simulated DOM and permit exams to
work together with the UI (JSDOM) in the identical means as a human person would. Widespread frontend frameworks use JSDOM
to run part exams in-process.
Extra hints on the way to get sub-millisecond end-to-end exams come from Aslak Hellesøy.
Coping with exterior methods
Enterprise purposes often depend upon exterior companies; an ecommerce software will seemingly want
to speak to cost gateways, mail servers, stock companies, and lots of others. This makes testing extra
sophisticated. If we tried to check the appliance end-to-end, linked to exterior companies, we might run
into many issues. The exterior companies may not be at all times accessible, they is likely to be sluggish and
unreliable, and they won’t have a take a look at model that we will use. And even when a take a look at setting of an
exterior service exists, it may not be handy to make use of for different causes.
I as soon as labored with a take a look at cost gateway, utilizing a take a look at bank card, and we needed to periodically name
the folks behind this service to replenish the credit score restrict of the take a look at card by a couple of million Euros,
as a result of even when our exams tried to “spend” as little as attainable, they had been working on a regular basis and so they
would frequently convey the accessible credit score restrict to zero. One other instance is a take a look at model of a inventory
alternate API that respects the actual market opening and shutting phases, in order that we will’t run the exams off
hours. Or they may have fee limiters.
It’s clear that one of many success standards with agentic coding is quick and dependable suggestions, so it’s
vital to have the ability to run our exams, even end-to-end exams, domestically with no connection to exterior
companies.
We will run native databases and
native electronic mail servers, however what about customized third get together companies?
The standard resolution is to setup a device like Wiremock or
Mountebank, with particular directions to mock the specified
behaviour. This works, however it’s loads of work to specify how
the exterior system ought to behave within the take a look at. An rising
method to this resolution is to get coding brokers to generate
native simulators of the exterior companies. If the exterior
service has a broadcast API, we will simply ask a coding agent to
implement it. This method was popularized by Justin McCarthy,
who calls them Digital Twins
(additionally see this interview video with McCarthy). This
method was additionally talked about in
this video presentation by Clare Liguori, who calls
them mock companies, within the context of how groups handle to get
a step enchancment in productiveness with coding brokers.
On this context, it is typically helpful to run the identical take a look at as an
in-process take a look at for fast suggestions, and as an
out-of course of integration take a look at with extra life like dependencies.
Checks-as-data makes this straightforward to do by
having AI generate totally different take a look at runners for a similar take a look at. The same method was defined by
Uberto Barbini utilizing tests-as-code, which makes it a bit much less simple to undertake.
The subject of the way to do black field exams with exterior dependencies is wealthy and deep and we
can however skim it on this article. Extra particulars may be present in
Martin Fowler’s or
Ham Vocke’s articles.
Defending the take a look at harness
One downside with coding brokers is that they might typically “cheat”; within the rush to assert job
completion, they may take shortcuts, akin to weakening or disabling exams. This is without doubt one of the causes
why builders, as we talked about within the introduction, may lose confidence within the safety afforded by
the exams, as they’re modified as a consequence of refactoring or as a consequence of new options being applied, and so they
are afraid that the exams is likely to be unexpectedly weakened within the course of.
The method described on this article helps with this downside, as a result of when the vital a part of
the exams is in textual content recordsdata, the builders can shield these recordsdata from
modification, when no adjustments to the spec are anticipated, or a minimum of, they’ll examine that these recordsdata are
not unexpectedly modified in supply management. So it is more durable for the builders to overlook a modification in
the exams, and if such a modification occurs, they’ll examine the tests-as-data to see what’s modified,
with hopefully much less fatigue than would occur if the exams had been tests-as-code.
| When | Anticipate manufacturing code adjustments? | Anticipate take a look at information adjustments? | Anticipate take a look at runner adjustments? |
|---|---|---|---|
| Implementing new performance | Sure | Sure | No |
| Refactoring manufacturing code | Sure | No | No |
| Bettering take a look at protection | No | Sure | No |
| Bettering take a look at DSL | No | Sure | Sure |
Relying on the kind of job, it is attainable to guard the recordsdata that we’re not anticipating the AI to
change, by making them read-only in a means that the agent can’t bypass, or by working a examine in CI
that verifies what recordsdata had been modified relying on the kind of job. The hooks facility of coding
harnesses can present the mannequin quick suggestions when it makes an attempt to alter one thing that it should not,
however is just not bullet-proof.
Even then, there may be nonetheless some room for AI to play surprises on us. The take a look at runner is code, and might be
unexpectedly modified. The DSL implementation additionally offers room for AI-induced confusion. To additional enhance our
confidence that the exams are nonetheless defending us, we would look into extra methods, akin to these talked about
within the subsequent part.
Validating the exams
When the AI writes some, or many of the exams, we nonetheless have a assessment downside. The methods described
above make take a look at assessment cheaper, by rising the expressiveness and conciseness of the exams. Nonetheless,
the amount of exams continues to be going to be important, so we incur cognitive fatigue in take a look at assessment, and
run the chance of cognitive give up.
Let’s examine two methods for coping with this. One is discovering methods to validate the exams; the opposite is
discovering extra methods to validate the product itself.
The very first thing we will do is mutation testing: we inject intentional faults in manufacturing code,
and see if any take a look at breaks, and if it breaks, examine that the error message is right and informative. The
easiest option to do mutation testing is to manually change one thing within the manufacturing code, e.g., flip a
+ right into a -, or remark out one department of an if, and see if any take a look at
breaks. Then we would ask AI to do some mutation testing itself. Lastly, we would undertake a mutation testing
library, to automate this course of and make it a part of a CI pipeline.
Mutation testing proves that the exams are efficient in detecting faults, however it doesn’t shield us
in opposition to the chance that the exams themselves are specifying one thing that isn’t right. As a way to
mitigate this danger, we must always search for methods to validate the exams themselves, i.e., to validate that the
anticipated output of the exams is right. An oracle is somebody or one thing that is ready to inform
what the proper output must be for any given enter. Generally the one accessible oracle is a
particular person: the area knowledgeable, however we will discover typically different oracles. One instance is official documentation:
official rules, inside compliance paperwork, technical handbooks, API docs.
As an example, within the improvement of a COBOL interpreter, I supplied the official IBM manuals, in pdf
and textual content format, in order that the brokers had an authoritative supply for the dialect of COBOL that runs on
IBM i machines.
One other sort of oracle is an alternate implementation: typically you should use a easy, brute pressure
algorithm to match the outputs of a posh, extra environment friendly algorithm. I’ve used the oracle method
within the improvement of the COBOL interpreter talked about above, the place all the client exams had been required to
go in the identical means on an actual IBM i system, as they had been passing on my laptop computer. I used it to validate
that the client exams, that had been largely generated by AI, had been specifying the identical behaviour because the IBM
machine.
That is a further benefit of tests-as-data: it’s possible you’ll run the identical take a look at in a couple of
setting, by getting AI to put in writing one other take a look at runner. That is helpful e.g., when rewriting a system, as
we will write characterization exams that may be run in opposition to each the outdated and new setting.
Past example-based exams
The exams we have now been discussing thus far are all example-based, which means that they train the system
by checking a particular instance of behaviour. Property-based testing is a very totally different and
complementary method. Property-based exams (PBT) train the system via a big, randomized
number of inputs, checking that no sequence of inputs pushes the system into an undesirable state. On the
very least we will examine that no enter produces a crash; extra refined approaches to PBT contain
checking system invariants, that’s, properties that should at all times maintain, like as an illustration buyer
steadiness must not ever be unfavourable, or examine the outcomes of the system with an oracle.
Relying on the character of your software, it’s possible you’ll discover inventive methods to additional take a look at and
improve confidence in its correctness. If it is a sport, have the AI play a whole bunch of video games in opposition to
itself. If it is a programming language compiler, have the AI implement a posh program in it and see
how effectively it runs. If it is a internet software, have the AI simulate customers and take a look at workflows by working the
browser via a device like agent-browser. Ask your coding
agent; it would provide you with some extra methods.
Limits of applicability
The methods described on this article are acceptable for testing manufacturing methods. Not all improvement efforts require, or profit from, this kind of therapy: when beginning one thing new, it may be good to generate a prototype and discover the house of potentialities, and observe what the coding agent produces after which ask for adjustments. Prototypes, proofs-of-concepts, experiments can all be generated rapidly with out an excessive amount of concern for exams, as a result of in an early stage, studying rapidly may be extra vital than having the ability to safely evolve the system.
As soon as we have now a greater understanding of what we would like, we will both throw away the prototype and rebuild it from scratch with exams, or we will stabilize the prototype and add take a look at protection after the actual fact.
The additional equipment and indirection of an exterior DSL requires further work to make sure that the DSL expresses effectively the issues that we need to say, and that the take a look at runner and the printers and parser are right. This work is sensible if we’re going to assessment these exams, a minimum of a pattern of them, to make sure that they categorical what we would like. However typically it would make extra sense to only let the mannequin write exams in whichever means it desires, as a result of it will be quicker and cheaper. This may make sense particularly when we have now different methods to validate that the system does what we would like.
The massive steps that these methods allow make it more durable for people to maintain a superb understanding of how the system works. An understanding of the inner structure of the product continues to be vital, and different methods are wanted for us to achieve and keep this understanding.
The approaches mentioned on this article are sometimes not ample to attain assurance that the system is right. Different automated testing methods can be utilized, as mentioned above. Most significantly, human exploratory testing is at all times really useful.
Conclusion
We began from the issue that many builders who give excessive autonomy to AI don’t assume that the take a look at protection they get is reliable, mainly as a result of AI-generated exams are arduous to learn and have a tendency to alter each time the manufacturing code is modified, even for refactorings.
We proposed an answer that consists of:
- Buyer exams that talk the language of the client (which these days consists of the builders)
- Black field exams on the system or part stage
- Tabular parameterized exams the place relevant,
- Advert hoc take a look at DSLs the place tables will not work
- Transferring the take a look at information (tables or eventualities) to textual content recordsdata which are straightforward to inform aside from take a look at code
- An AI-generated take a look at runner that runs take a look at information recordsdata
This helps the issue of take a look at trustworthiness, as a result of the exams turn out to be extra expressive, devoid of irrelevant particulars, strong with respect to refactoring and simpler to guard from sudden adjustments by the coding brokers. It additionally helps to put in writing specs that depend on greater than Markdown prose to make sure the behaviour we would like is applied appropriately.
These methods assist set up readability on the useful specification of the system; they’re part of an engineering harness, and they need to be paired with different complementary methods, together with: mutation testing, property-based exams, lints and scanners and handbook exploratory testing by people.
That is related now, as a result of evidently going ahead, most code will likely be written by machines, and that features take a look at code. We have to form these exams in a means that helps folks keep in management.
We will get began making use of these concepts by casting our exams within the language of the client and following the method outlined above for Constrained Checks.

